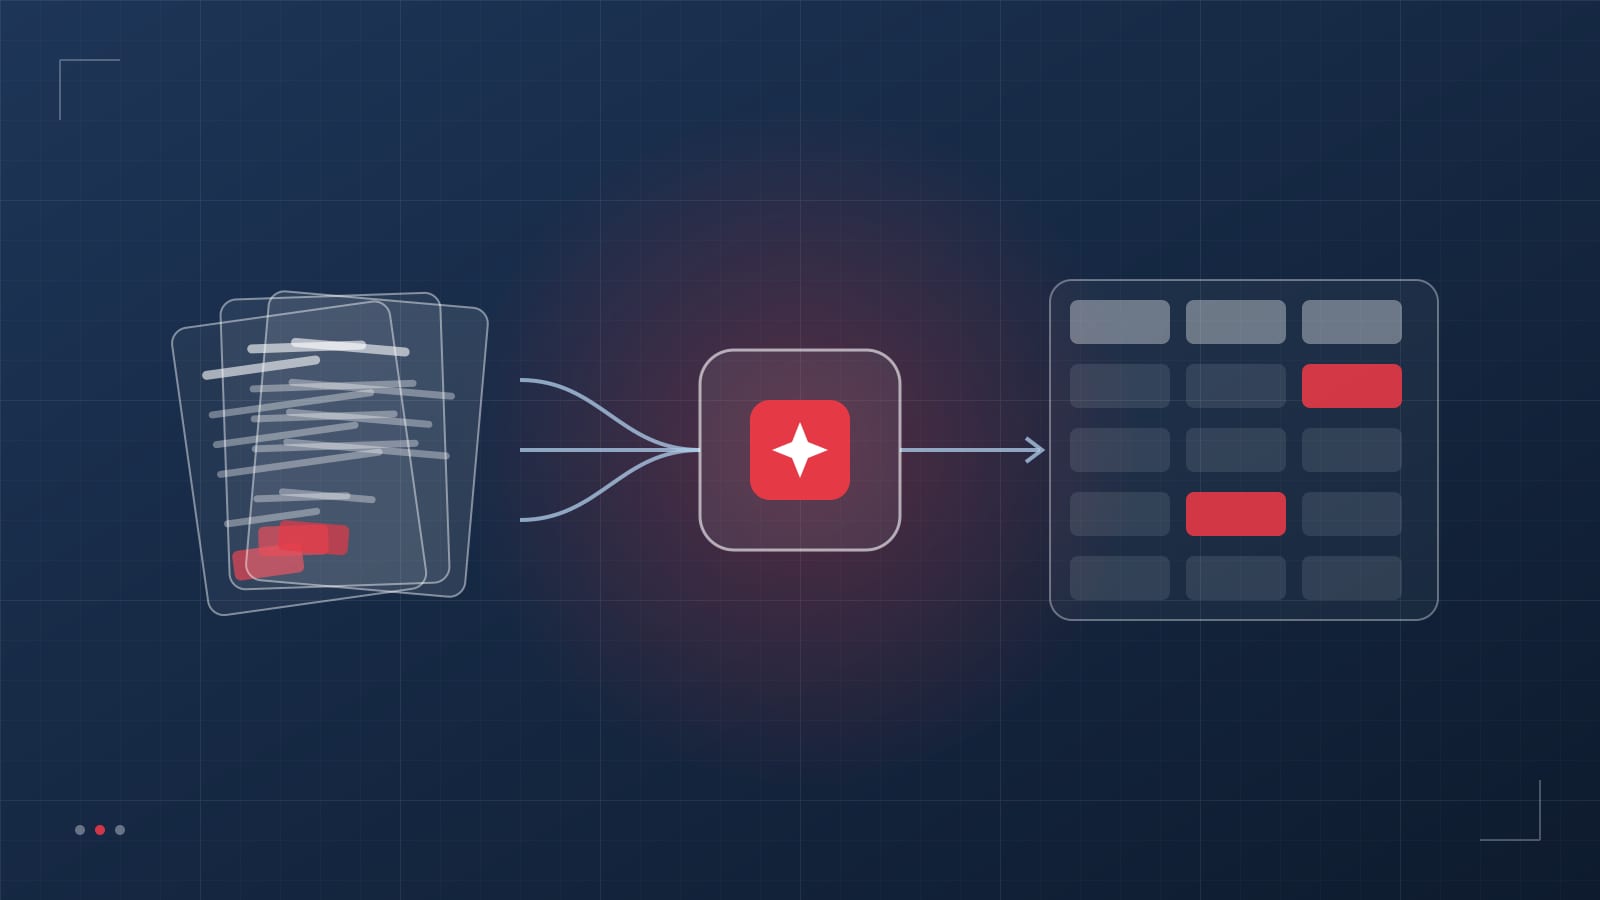
- Large language models with vision now read unstructured and handwritten documents that template OCR never could.
- Extraction is only half the job: validation, confidence scoring, and routing decide how much you can safely automate.
- Automate the routine claims fully and send complex ones to people. Keep humans on every adverse decision.
- Track straight-through processing rate, field accuracy, and cycle time from day one.
Ask any claims leader where time goes and the answer is rarely the decision itself. It is the intake: opening emails, reading attachments, re-keying policy numbers and dates, chasing missing documents, and deciding who should handle what. That work is slow, error-prone, and exactly what document AI has become good at.
Why intake is the bottleneck
- Documents arrive through many channels — email, portals, brokers, mail scanning — in every format
- The same field appears in different places on forms from different sources
- Supporting evidence includes photos, invoices, medical bills, police reports, and handwritten notes
- Every manual touch adds days to cycle time, and every typo creates rework downstream
Three generations of document processing
| Approach | How it works | Where it struggles |
|---|---|---|
| Template OCR | Reads text from fixed positions on known forms | Any new layout, handwriting, or free text |
| Machine-learning IDP | Models trained to find fields across similar documents | Needs labelled training data for each document type |
| LLM and multimodal extraction | Models that read the document like a person and return structured data from instructions | Needs validation and confidence checks; cost per page must be managed |
The practical answer in 2026 is usually a mix: cheap, fast OCR where documents are standard, and LLM-based extraction for the long tail of varied and unstructured documents.
The claims intake pipeline
- Ingest. Capture documents from every channel into one queue, with the original preserved for audit.
- Classify. Identify each document type — first notice of loss, invoice, estimate, medical record, photo — and split multi-document PDFs.
- Extract. Pull the fields each type needs: policy number, dates, amounts, parties, loss description.
- Validate. Check every value against the policy administration system and business rules: is the policy active on the loss date, does the amount match the invoice total, is anything missing?
- Score and route. Combine model confidence and validation results to decide: process automatically, send for quick review, or route to an adjuster.
- Review. Give reviewers a screen that shows the document and the extracted fields side by side, so a correction takes seconds.
- Learn. Feed corrections back into prompts, rules, and evaluation sets so accuracy improves over time.
Straight-through processing: automate what is safe
The goal is not to automate every claim. It is to let routine, low-risk claims flow through without anyone touching them, so experienced staff spend their time on the complex ones.
On the broker and claims platform we built for Argo Global Insurance, 85% of claims now flow through automatically and only complex claims need people — saving $500K a year compared with the manual process. The automation rate came from process design as much as technology: one clean intake path, strong validation rules, and clear routing for exceptions.
Metrics that matter
| Metric | What it tells you |
|---|---|
| Straight-through processing rate | Share of claims completed with no manual touch |
| Field-level accuracy | How often each extracted field is correct, measured on real samples |
| Cycle time | Days from first notice to decision or payment |
| Touch time per claim | Staff minutes spent on each claim, including review |
| Exception rate by reason | Where documents or rules cause the most manual work |
Capture a baseline for each before you start. Without one, it is impossible to prove the value.
Compliance, privacy, and fairness
- Claims documents contain personal, financial, and sometimes health data. Process them in your own cloud environment with encryption, access control, and retention rules — see our guide to private AI.
- Keep a full audit trail: original document, extracted values, corrections, and who approved what.
- Use AI to prepare and recommend, not to deny. Adverse decisions should always be made — and explainable — by a person.
- Treat claims AI as a higher-risk use case in your AI governance programme, with regular accuracy and bias testing.
The same pipeline applies well beyond claims: underwriting submissions, loss runs, broker emails, and invoices in insurance, and referral and intake packets in healthcare.
Frequently asked questions
How accurate is LLM-based document extraction?
On typical claims documents, modern multimodal models extract common fields very accurately, but accuracy varies by document type and field. The right approach is to measure field-level accuracy on your own documents, validate every extracted value against business rules and source systems, and route low-confidence results to a person.
Can intelligent document processing read handwriting and photos?
Modern multimodal models handle handwriting, phone photos, and poor scans far better than template OCR did. Very poor images still need human review, which is why confidence scoring and an efficient review screen are part of any production design.
Do we need to replace our claims system?
No. Document processing sits in front of your existing core system — whether that is a commercial platform or an in-house application — and passes validated data into it through APIs or integration queues. Your system of record stays the same.
Which documents should we automate first?
Start with the highest-volume document type that has clear fields and a well-defined next step — often first notice of loss forms, invoices, or standard supporting documents. Leave complex, low-volume documents for later phases.